Opinion
15 injured at Phantasialand. Outlook outage blocks chlorine warnings.
A pool operator must plan for email outages. Guests' safety cannot depend on Microsoft working at that moment. An opinion by Julian Köhn.
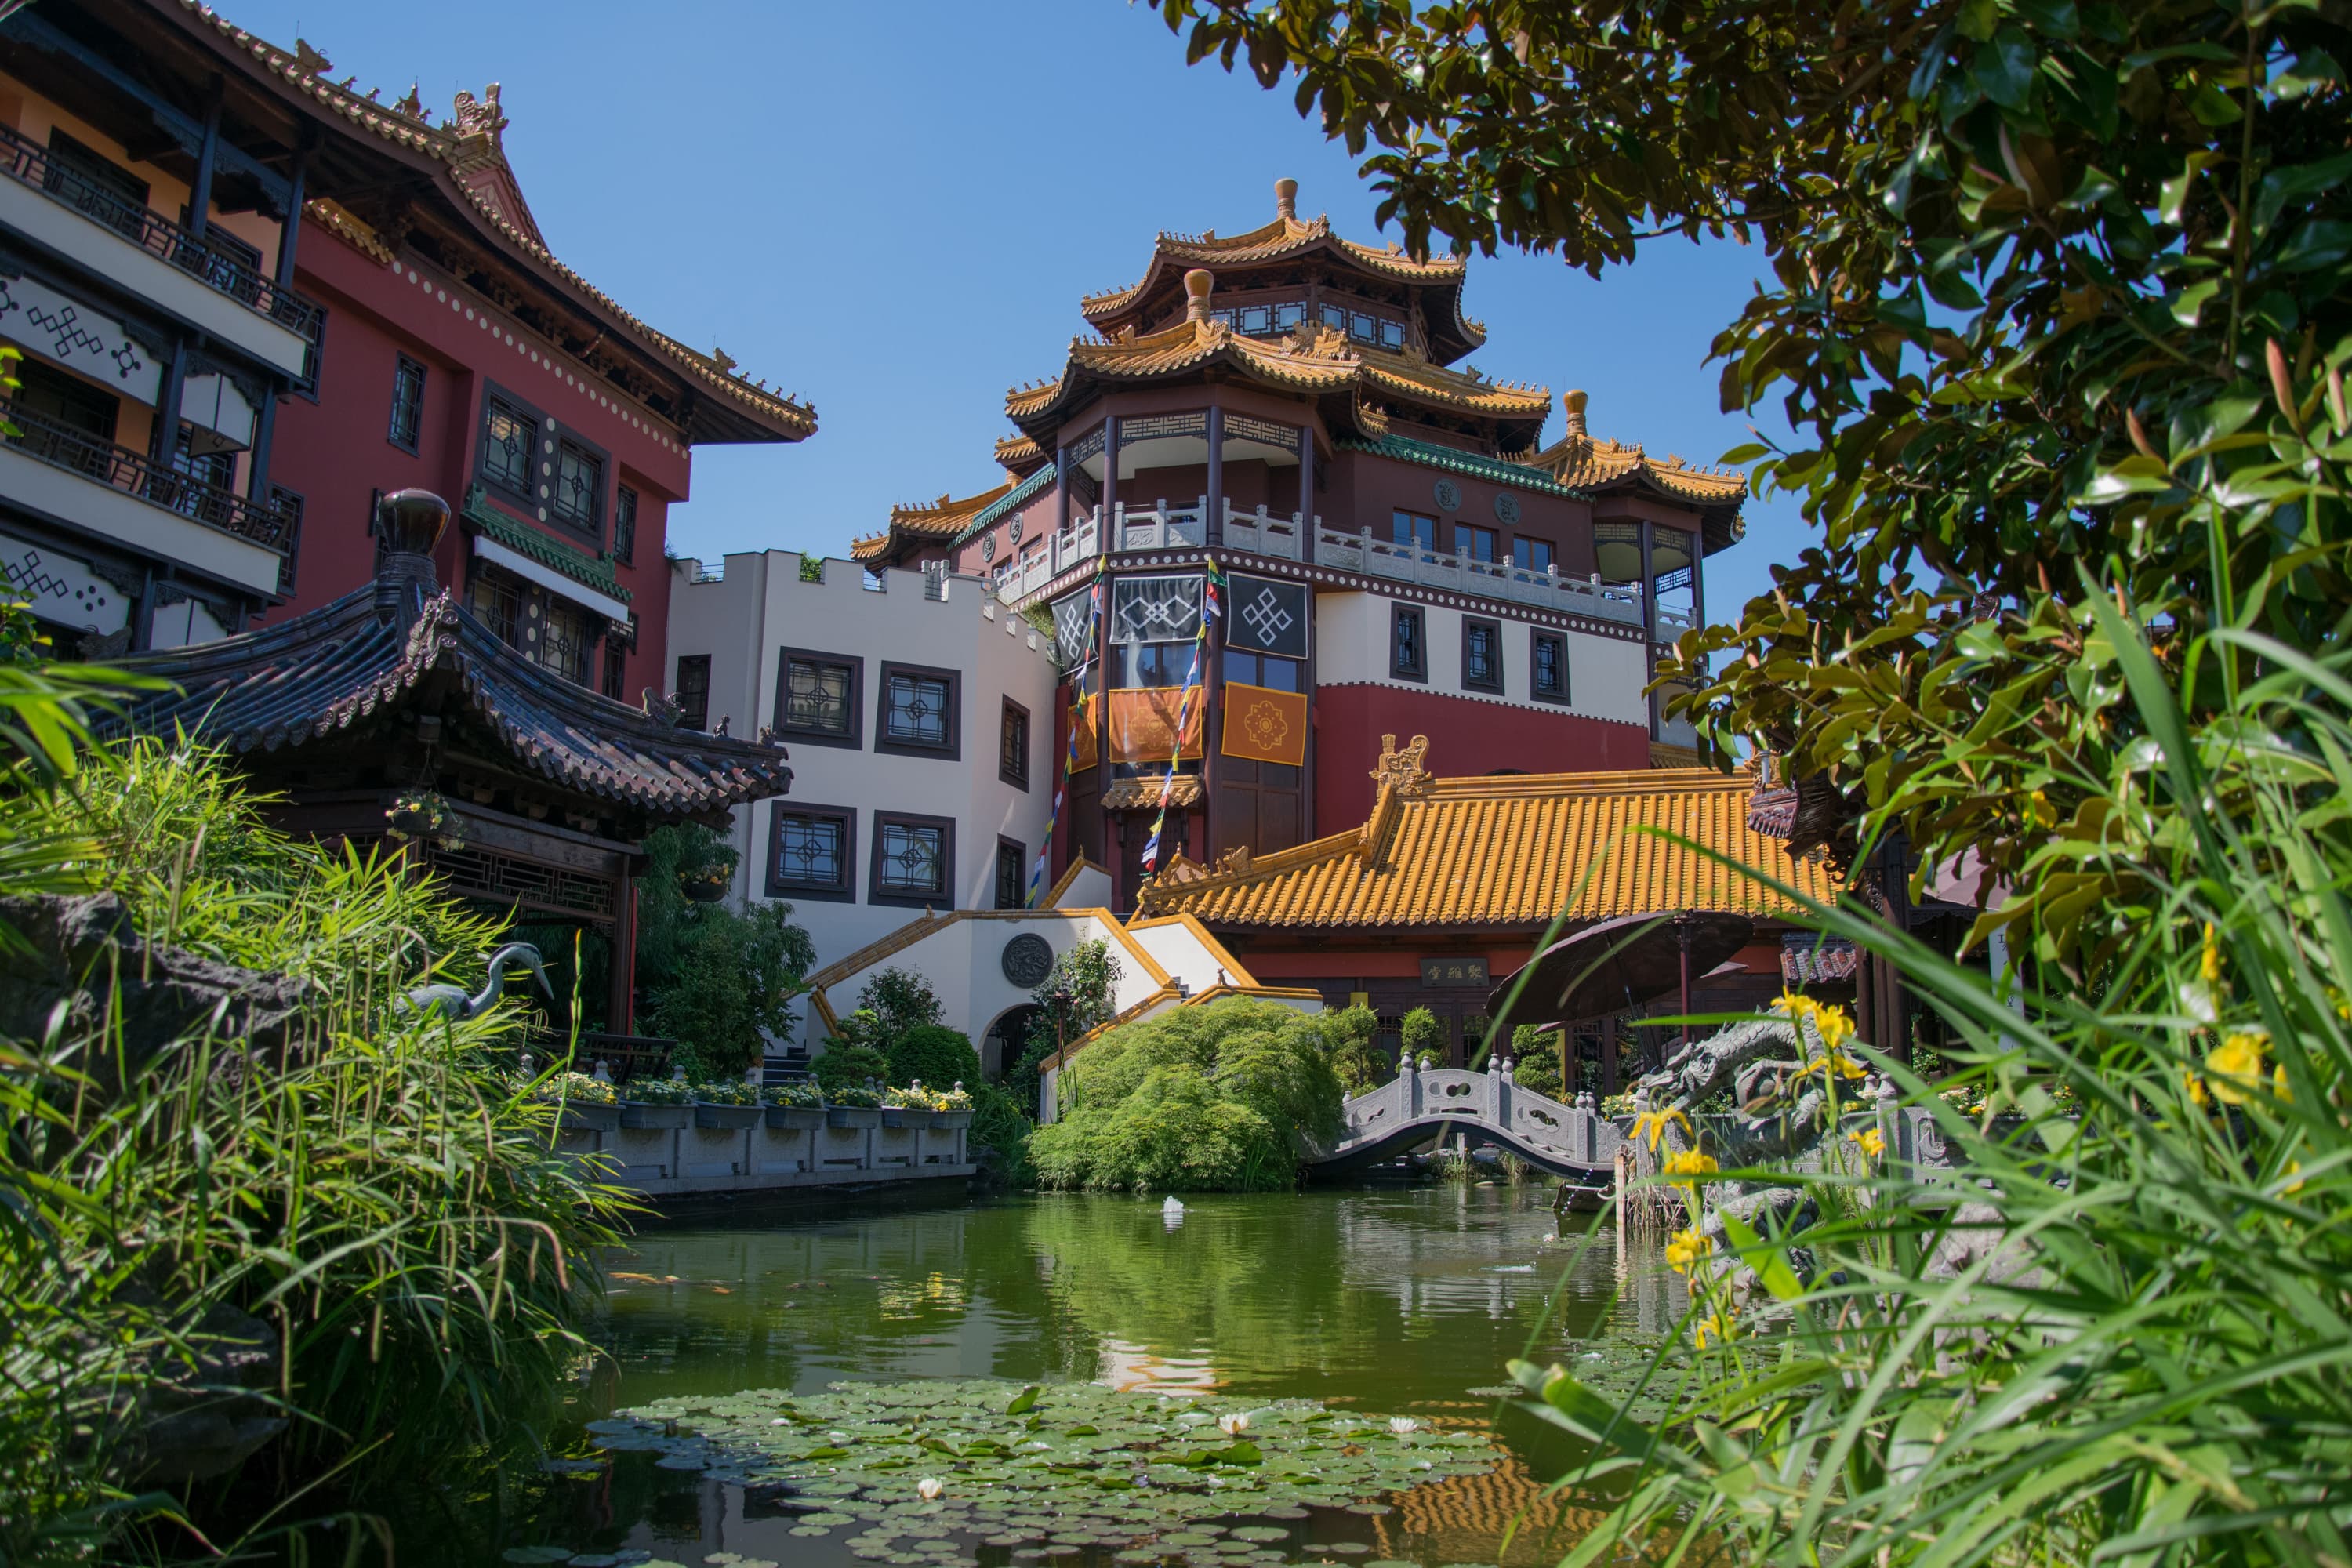
Archive photo 2019 Photo Phantasialand DE CC BY-SA 4.0 Image credit
- Original title
- Hotel-Ling-Bao.jpg
- Photographer
- Phantasialand DE
- Photographed
- 23 September 2019
- Source
- Wikimedia Commons
- Licence
- CC BY-SA 4.0


A pool operator must plan for email outages. Guests' safety cannot depend on Microsoft working at that moment.
On Friday, 13 November 2026, 15 guests were injured at the pool in Phantasialand's Ling Bao hotel, with four taken to hospital. A faulty dosing system had added too much chlorine. Phantasialand told WDR that warning emails had not arrived because of the Outlook outage.
When an alert warns of a dangerous chlorine concentration, the response on site determines whether people are protected. If an email outage interrupts that response, pointing to the unavailable provider is inadequate. The operator must ensure that its safety procedures remain effective under those conditions.
The operator must plan for the outage
Microsoft is responsible for the reliability of its services. An organisation that incorporates those services into a safety-critical process must nevertheless anticipate their failure and manage the consequences for its own operations. A cloud contract does not remove that responsibility from a hotel operator.
Temporary loss of an email service is a foreseeable operational risk. An organisation that uses it for critical warnings must therefore establish in advance how an alert will still reach someone with the authority and ability to intervene in time.
Alerting involves more than technical delivery. If nobody acknowledges a warning, the procedure must reach another person or trigger a defined protective response. The appropriate response and the time available depend on the specific hazard. A log entry marked "sent" answers none of those questions.
Cloud services do not take over safety planning
Business continuity management, or BCM, must establish which processes need to keep working during an outage and how to maintain them. Preparation includes alternative alerting routes and exercises to test reachability and response times, as described in chapters 5.2 and 13.8 of BSI Standard 200-4. For safety-critical operations, it must also be clear when to restrict or stop activities because the required protection can no longer be assured.
For dosing equipment, simply adding another notification channel is therefore insufficient. Qualified specialists need to consider the equipment's protective functions together with the procedures for responding to a fault. The DGUV rules for operating swimming pools address hazard assessment, operating instructions and the safe functioning of work equipment. A warning should enable timely action; it cannot replace a protective function that the equipment requires.
Two apps can share the same point of failure
An alerting app alongside an email inbox initially looks like an additional safeguard. But if it retrieves its notifications from that same inbox, it inherits the risk of the mailbox failing. The same problem arises when apparently separate warning routes depend on one server or internet connection.
During a review, I would therefore follow the entire route, from the system triggering the alert through transmission to the responsible person. What matters is which dependencies the fallback actually avoids and whether it still works under the assumed failure conditions.
That review must also include the people expected to respond. A notification on the phone of someone who cannot be reached is no more useful than an undeliverable email. Deputies and escalation therefore belong in the same procedure and must work without anyone first having to search the unavailable system for a phone number.
The test ends with a response
A fallback deserves confidence once the people involved have exercised it under the failure conditions it is meant to address. A controlled exercise using test signals can assume that the normal email service is unavailable. The procedure must then demonstrate that the message arrives in time, someone acknowledges it and the required decision is made.
The exercise also needs to cover the first person contacted failing to respond. The measured time until someone takes responsibility must meet the response time that qualified specialists have determined for the hazard. A message answered after twenty minutes would be worthless if the safety design required intervention within a few minutes.
Any gaps found need an owner, a correction and another test. Only then does a documented weakness become a demonstrably resolved one. We have described how to check cloud dependencies and fallback arrangements in your own operations using a business process as an example.
An uptime figure is not enough when people are at risk
A cloud outage can interrupt customer contact and sales, but safety-critical operations involve different consequences. Where a delayed response could put people at risk, decisions about safeguards must start with that possible harm. A provider's high average availability does not answer what happens during the remaining downtime.
Operational and executive management must therefore provide the resources for effective safeguards and alerting routes and have their effectiveness tested. They must also establish the conditions under which operations remain safe and who stops them when those conditions no longer hold.
Guests must be able to trust the operator to provide for their safety. That trust cannot depend on whether Outlook happens to be delivering email.
Sources
- WDR: Chlorine incident at Phantasialand [Accessed ]
- BSI Standard 200-4: Business Continuity Management [Accessed ]
- DGUV Rule 107-001: Operation of swimming pools [Accessed ]